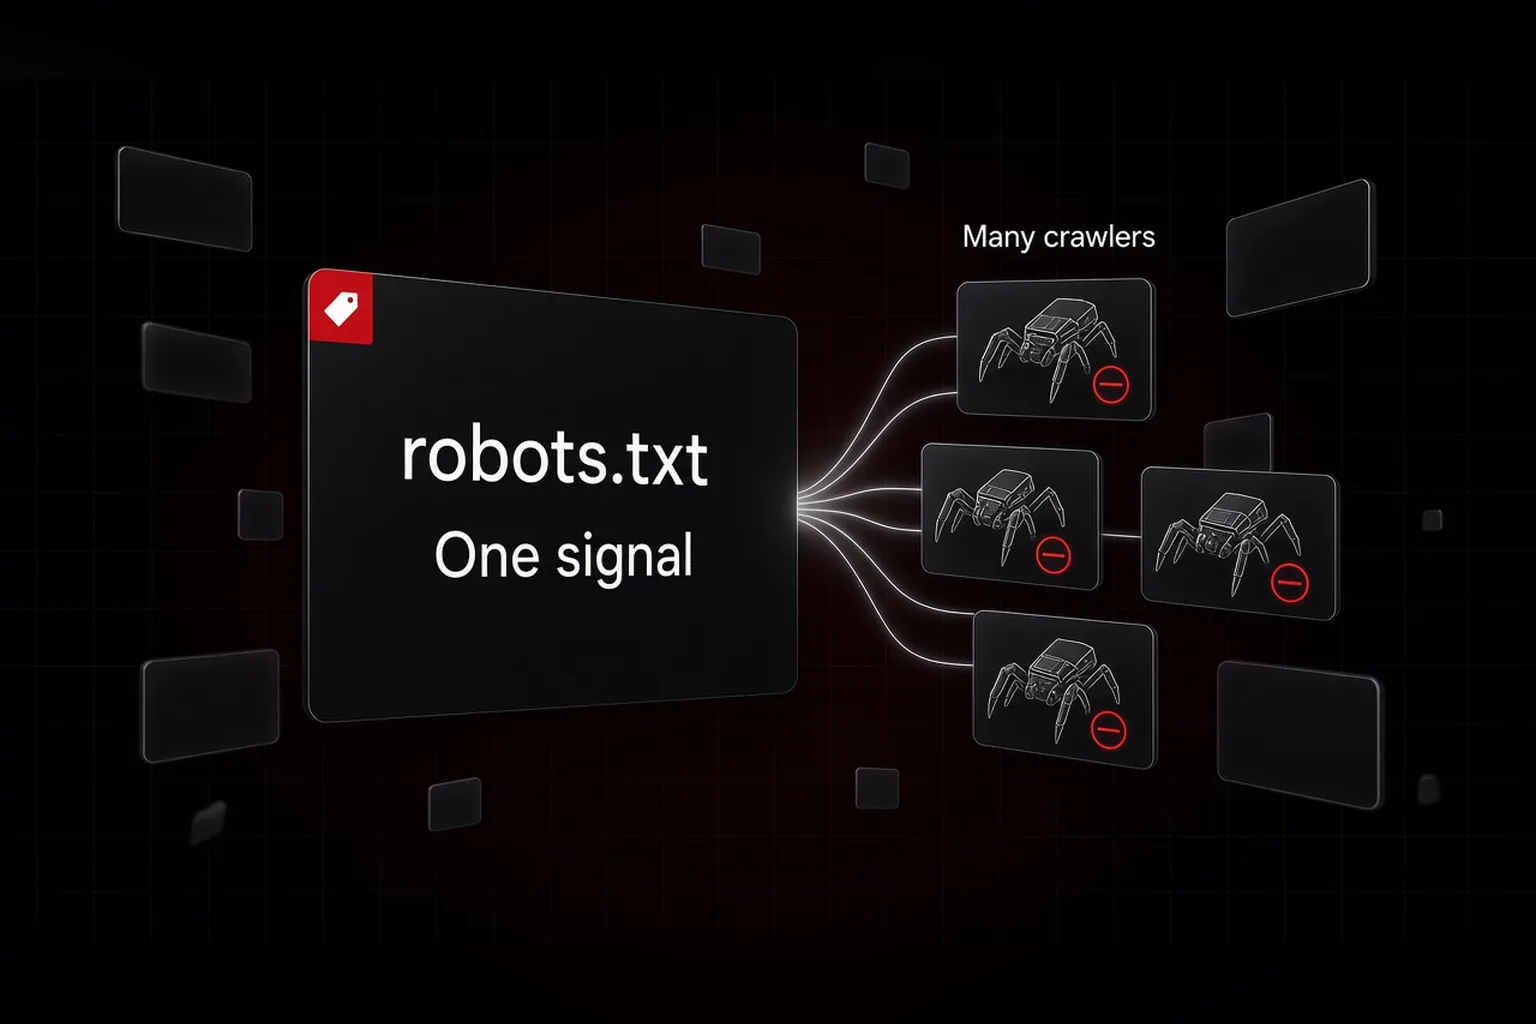
OpenAI, Google, Microsoft and Anthropic say they will honour a shared signal in robots.txt that lets website operators state whether their content may be used for AI training, The Verge reported on October 30, 2026. Until now, sites have had to set these preferences separately for each company's crawlers.
The signal is a "policy token" proposed within the Internet Engineering Task Force by Kevin Kelley, a technical lead for standards at Anthropic. It draws on the work of the IETF's AI Preferences working group. In its own announcement, OpenAI says the signal covers the use of content for foundational generative AI training, and that it will not replace the crawler controls OpenAI already offers, which continue to apply.
Timing differs by company. Anthropic has already adopted the signal. OpenAI aims to implement it "in the coming months" and will publish details when it does. Google and Microsoft plan to support it next year. Microsoft says it will offer separate controls for opting out of AI training and of AI grounding, and that sites will appear in Bing search results whatever they choose. Meta's communications head Andy Stone voiced support but did not say whether Meta will honour the signal.
The effort is voluntary. Like everything in robots.txt, it works only for crawlers that choose to respect the file. It also addresses training, which is one use among several. Microsoft's split between training and grounding shows the line: using a page to build a model and retrieving it to answer a question are different uses, with different effects on a site's traffic.
Why this matters for website owners
For a company website, one line in robots.txt may soon replace a list of crawler names that changes every few months. The decision itself stays the same: whether to allow training, and separately whether to stay visible in search and in AI answers. The exact syntax will matter once providers publish their implementations. Until then, existing per-crawler rules remain the working control.
This article is not legal advice.